One-tap capture
Tap the mic. Audio streams to Hume's prosody model and the top emotions update in real time alongside a rolling chart and a session timer.
Emovo is a cross-platform system that streams your microphone audio to a hosted prosody AI model and renders the resulting emotion scores live — then archives each session for replay and long-term analytics. iOS, Android, and the web. One backend.
Speech prosody — pitch, intensity, rhythm, voice quality — carries a rich emotional signal that listeners decode unconsciously. Mainstream wellness apps rely on self-report (mood journals, PHQ-9), which is reflective and low-frequency by design.
Tap the mic. Audio streams to Hume's prosody model and the top emotions update in real time alongside a rolling chart and a session timer.
Every session saves the audio plus per-second emotion snapshots. Scrub the timeline and the chart, top emotion, and bars all re-synchronize to the playhead.
Streaks, mood-trend lines, duration-weighted top emotions, a 15-week × 7-day activity heatmap, and a peak-moments feed across all your sessions.
Both clients (Flutter mobile, React web) talk to a single Firebase backend for auth, data, files, hosting, and telemetry. A Firebase-Auth-protected Cloud Function provisions a per-session Hume credential, after which each client streams 1-second audio chunks directly to Hume's expression-measurement WebSocket and receives back emotion-score predictions in real time.


 Firebase Backend
A deliberate, narrow set of technologies — chosen so the same data contract serves mobile and web with no per-platform plumbing.
Flutter
 Dart
React 18
 TypeScript
 Vite
 MUI v6
Firebase
 Cloud Functions
 Node 22
 iOS
 Android
Every feature lives on every platform. Sessions saved on the phone replay seamlessly on the web — and vice-versa.
Gradient card for the dominant emotion with a delta arrow. A rolling 3-emotion line chart. Animated top-5 bars. A clean session timer. One-tap to start, one-tap to stop.
record package (mobile)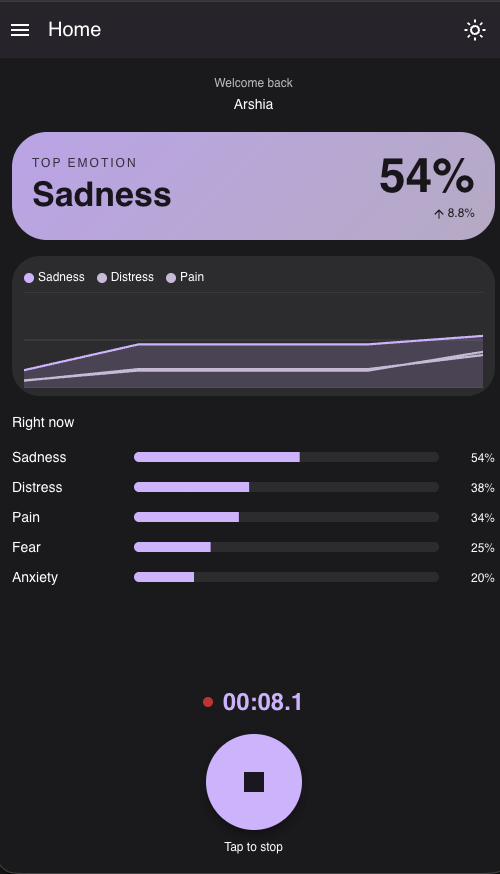
Every completed session is stored with its full audio and per-second emotion scores. Tap a peak moment to jump straight to it. The chart, top-emotion card, and right-now bars all re-synchronize to the playhead.

Streak, session count, total minutes. Mood-trend line chart over the three dominant emotions. Duration-weighted top-emotions bars. A 15-week × 7-day activity heatmap. A cross-session peak feed.
onSnapshot · push updates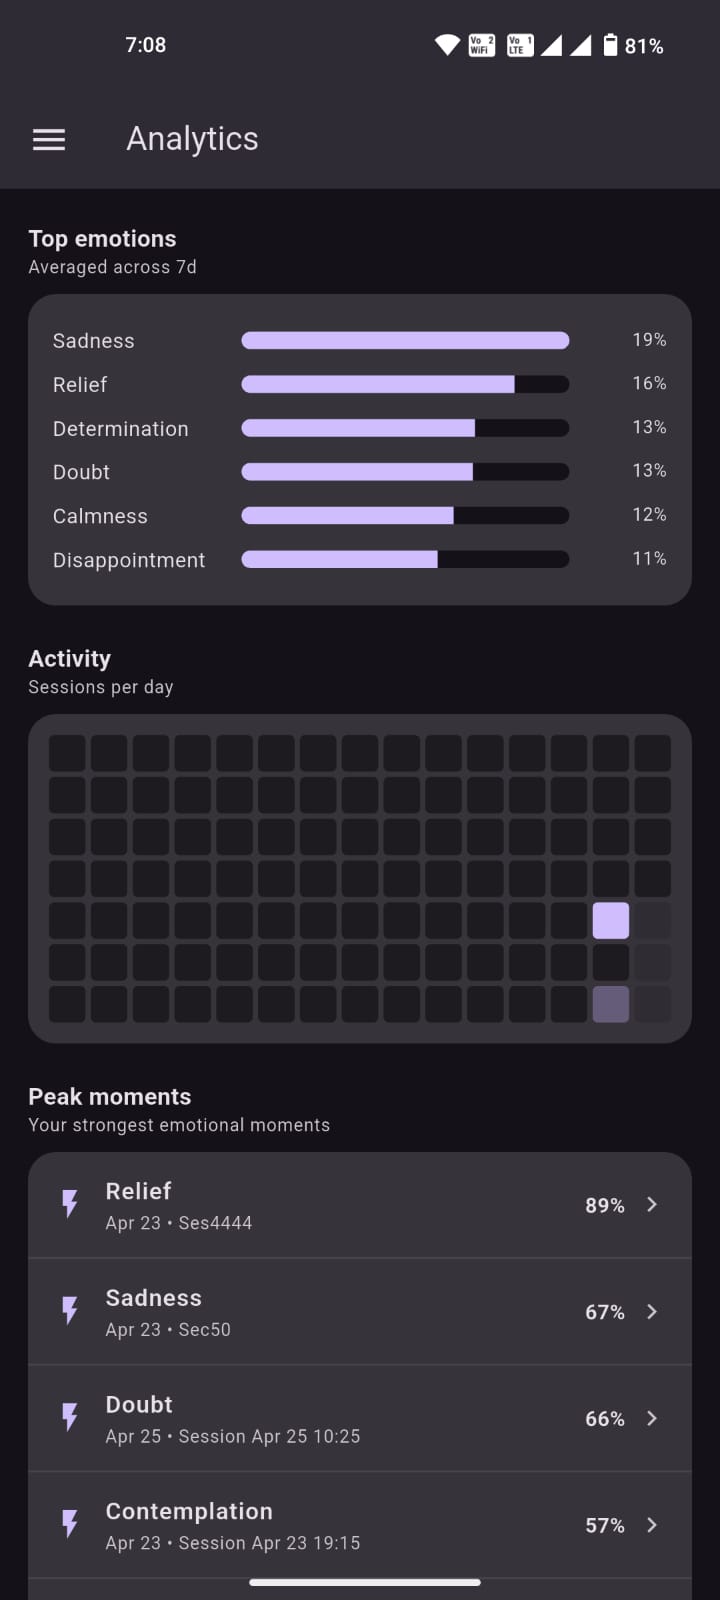
Audio is captured natively, resampled to 16 kHz mono Int16 PCM inside the audio thread.
Each 1-second chunk is wrapped in a WAV header, base-64 encoded
and sent over a WebSocket with a payload_id.
Hume analyzes each chunk against a 5-second context so prosody continuity isn't lost between chunks.
Predictions arrive asynchronously and feed the rolling chart, top-emotion gradient, and animated bars at 60 fps.
On stop, the full PCM is wrapped into a single WAV, uploaded to Cloud Storage, and a session document is written to Firestore.
AudioContext starts suspended
Defensive audioCtx.resume() after the user-gesture so
the worklet never silently no-ops.
Use Hume's 5 s sliding window so each 1 s chunk is analyzed against continuous voiced context.
Tag every snapshot with the cumulative PCM byte count → exact audio-clock offset for playback sync.
Single source-of-truth Firestore schema; mirrored module structure;
same Material-3 seed colour #6750A4.
End-to-end realtime emotion streaming with sub-second visible latency on every platform — and full feature parity across iOS, Android, and web.
Weekly / monthly aggregates, day-of-week effects, calendar overlays.
Integrate Hume's conversational EVI endpoint for two-way voice interaction.
Lightweight prosody models for offline / privacy-preserving capture.
Native PWA install on web; background-recording on mobile.
Does passive voice tracking improve emotional self-awareness vs. mood-journal baselines?
Two builds, one experience. Pick the device in your hand and start a session in under five seconds.

web.pngassets/qr/
mobile.pngassets/qr/